In my previous post, I dug into how LLMs went
from ELIZA’s if-then rules to “guess the next word”. OK, that explains the chat part. But there
was still one thing I didn’t get.
When I type fix the failing test in Claude Code, something runs my tests, reads three files, edits
one of them, runs the tests again and tells me it’s done. But a next-word predictor can’t open a
file. So who is doing all that?
I spent a few evenings reading some source code and building my own (very dumb) agent. It turns out it’s way simpler than I thought.
The model never touches your files
The LLM is just a function: text goes in, text comes out. It runs somewhere in a data centre, it has no access to your disk, your shell or your network, and it forgets everything as soon as it answers.
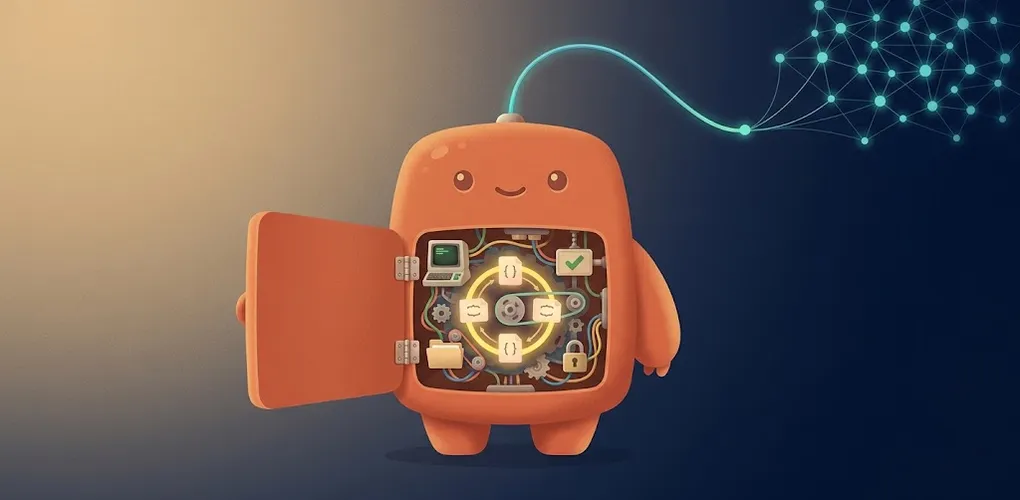
The part that actually does things is a regular program running on your machine. It’s called the harness (some people say agent runtime or scaffold). Claude Code, Codex CLI, Cursor’s agent mode… they’re all harnesses. The UI is different, but under the hood it’s the same 3 layers:
So when you say “the AI edited my file”, what really happened is: the model asked to edit the file, and the harness did it. I know, it sounds like nitpicking. But everything else in this post is built on top of this idea.
Tools: a contract written in JSON
How does a model “ask” for something? With tools (also known as “function calling”). On every request, the harness sends a list of tools to the model. Each tool has a name, a description, and a JSON Schema for the arguments:
{ "name": "read_file", "description": "Read the contents of a file at the given relative path. Use this when you want to see what's inside a file.", "input_schema": { "type": "object", "properties": { "path": { "type": "string", "description": "Relative path of the file" } }, "required": ["path"] }}The description is written for the model, not for you. It’s the only documentation the model gets. That’s why people spend so much time tweaking these sentences.
Then, instead of answering with text, the model can answer with a block that basically says “please call this tool with these arguments”:
{ "role": "assistant", "stop_reason": "tool_use", "content": [ { "type": "text", "text": "Let me look at the implementation first." }, { "type": "tool_use", "id": "toolu_01", "name": "read_file", "input": { "path": "src/utils/slugify.ts" } } ]}See the stop_reason: "tool_use"? The model stopped because it’s waiting for something. At this
point, nothing has been read yet. Now it’s the harness’s job to:
- Parse the
tool_useblock - Find the matching function in its own code and run it (this is where the file actually gets read)
- Send the output back as a
tool_resultmessage, with the sameidso the model can match the answer to the question
{ "role": "user", "content": [ { "type": "tool_result", "tool_use_id": "toolu_01", "content": "export function slugify(input: string): string {\n return input..." } ]}That’s it. The model asks, the harness runs it and replies. The model was trained on tons of these exchanges, so it’s pretty good at knowing when to use a tool, which one, and what to do with the result. But in the end, it’s just JSON going back and forth.
The loop
One tool call doesn’t make an agent. What turns it into an agent is a while loop. Seriously.
On every iteration, the harness sends the whole conversation to the model: system prompt, tools,
your prompt, every tool call and every tool result. The model reads everything and decides the next
step. If it’s a tool call, the harness runs it, adds the result to the conversation, and loops
again. If the model answers with text and stop_reason: "end_turn", the loop stops and you get the
answer.
I was expecting some kind of planner, a task graph, or a state machine saying “now we’re in the testing phase”. There’s nothing like that. The model decides what to do next, one step at a time, based on what it just saw.
This pattern even has a name: ReAct (Reason + Act), from a
2022 paper. The model thinks, acts, observes the result, and
repeats. Back then, it needed a lot of prompt tricks. Today, models are trained for it, and the API
gives you the tool_use / tool_result blocks out of the box.
To make it more concrete, I recorded a session. Click through it to see the loop in action. You can also switch to “Raw API messages” to see what the harness really sends:
You send a request. The harness adds it to the transcript and calls the model.
A few things I noticed:
- 1 step = 1 API call. Fixing one test took 5 calls. A real feature can easily take a hundred.
- The model doesn’t plan ahead. It ran the test first because that’s what any dev would do. Not because a rule told it to. Everything it “knows” about the task comes from the tool results.
- It’s a feedback loop. The model does something, gets an answer (a stack trace, a diff, green tests), and uses it for the next step. If an edit is wrong, it will see it in the next tool result and fix it. You don’t get this with a one-shot “write me the code” prompt.
- The conversation only grows. Every tool result is added to it, and the harness sends everything again on every call. That’s the agent’s only memory. What happens when it’s full? I’ll keep that for another post 😉
Let’s build our own agent
To make sure I got it right, I wrote a tiny agent (heavily inspired by Thorsten Ball’s
How to Build an Agent). If I remove the tools and the
CLI stuff, the whole harness fits in one while:
const messages: Anthropic.MessageParam[] = [{ role: 'user', content: userPrompt }]
while (true) {  const response = await client.messages.create({    model: 'claude-opus-5-5',    max_tokens: 16000,    system: 'You are a coding assistant. Use the tools to inspect and change the project.',    tools,    messages,  })
  // Keep the full assistant turn so the model sees its own previous tool calls  messages.push({ role: 'assistant', content: response.content })
  if (response.stop_reason !== 'tool_use') break
  const results: Anthropic.ToolResultBlockParam[] = []  for (const block of response.content) {    if (block.type !== 'tool_use') continue    try {      results.push({        type: 'tool_result',        tool_use_id: block.id,        content: runTool(block.name, block.input),      })    } catch (err) {      results.push({        type: 'tool_result',        tool_use_id: block.id,        content: String(err),        is_error: true,      })    }  }  messages.push({ role: 'user', content: results })}
runTool is a switch with 4 functions: list_files, read_file, write_file and run_command.
The whole file is ~100 lines, and it works! I pointed it at a small project, asked it to fix a bug,
and watched it list the files, read the right one, rewrite it and run the tests. I had the same
“there’s a tiny someone in my laptop” feeling as the first time I used ChatGPT. Except this time, I
wrote the laptop part myself, so I knew exactly how dumb it was.
One detail: when a tool throws, we don’t crash. We send the error back with is_error: true. This
is how the agent knows the test failed. Without it, the agent would be blind.
The full agent.ts, tools included
import Anthropic from '@anthropic-ai/sdk'import { execSync } from 'node:child_process'import { readFileSync, readdirSync, writeFileSync } from 'node:fs'import { createInterface } from 'node:readline/promises'
const client = new Anthropic()
// 1. The tools: a schema for the model, a function for the harnessconst tools: Anthropic.Tool[] = [  {    name: 'list_files',    description: 'List files and directories at a given path.',    input_schema: {      type: 'object',      properties: { path: { type: 'string', description: 'Directory to list, defaults to "."' } },    },  },  {    name: 'read_file',    description: 'Read the contents of a file at a relative path.',    input_schema: {      type: 'object',      properties: { path: { type: 'string' } },      required: ['path'],    },  },  {    name: 'write_file',    description: 'Overwrite a file with new content. Creates it if missing.',    input_schema: {      type: 'object',      properties: { path: { type: 'string' }, content: { type: 'string' } },      required: ['path', 'content'],    },  },  {    name: 'run_command',    description: 'Run a shell command and return stdout and stderr. Use it to run tests.',    input_schema: {      type: 'object',      properties: { command: { type: 'string' } },      required: ['command'],    },  },]
function runTool(name: string, input: Record<string, string>): string {  switch (name) {    case 'list_files':      return readdirSync(input.path ?? '.').join('\n')    case 'read_file':      return readFileSync(input.path, 'utf8')    case 'write_file':      writeFileSync(input.path, input.content)      return `Wrote ${input.path}`    case 'run_command':      return execSync(input.command, { encoding: 'utf8', stdio: 'pipe' })    default:      return `Unknown tool: ${name}`  }}
// 2. The loopasync function agent(userPrompt: string): Promise<void> {  const messages: Anthropic.MessageParam[] = [{ role: 'user', content: userPrompt }]
  while (true) {    const response = await client.messages.create({      model: 'claude-opus-5-5',      max_tokens: 16000,      system: `        You are a coding assistant working in the current directory.        Use the tools to inspect and change the project.        Run the tests to verify your changes.      `,      tools,      messages,    })
    messages.push({ role: 'assistant', content: response.content })
    for (const block of response.content) {      if (block.type === 'text') console.log(`\n🤖 ${block.text}`)    }
    if (response.stop_reason !== 'tool_use') break
    const results: Anthropic.ToolResultBlockParam[] = []    for (const block of response.content) {      if (block.type !== 'tool_use') continue      console.log(`🔧 ${block.name}(${JSON.stringify(block.input)})`)      try {        results.push({          type: 'tool_result',          tool_use_id: block.id,          content: runTool(block.name, block.input as Record<string, string>),        })      } catch (err) {        results.push({          type: 'tool_result',          tool_use_id: block.id,          content: String(err),          is_error: true,        })      }    }    messages.push({ role: 'user', content: results })  }}
const rl = createInterface({ input: process.stdin, output: process.stdout })await agent(await rl.question('What should I do? '))rl.close()
To run it, you need an Anthropic API key:
npm init -y && npm pkg set type=modulenpm install @anthropic-ai/sdkexport ANTHROPIC_API_KEY=sk-ant-...npx tsx agent.tsWho’s in charge: permissions
Back to run_command. The model can send rm -rf ~ as easily as npm test. It’s not evil, but it
makes mistakes. It also reads a lot of random text: a dependency’s README, a GitHub issue, the
output of curl… Any of these can contain “instructions”, and the model can’t always tell the
difference between something it reads and an order it receives. This is called prompt injection,
and nobody has fully fixed it yet.
So the harness has to keep an eye on it. Since every action goes through runTool, this is where
the checks happen:
- Permission prompts: reading a file is fine. But running a command or editing a file? It asks
you first. It’s the
Allow? (y/n)prompt you keep smashing. - Allowlists and denylists: “always allow
npm test”, “never touch.env”. These rules are checked before the tool runs, so you don’t get asked 200 times. - Sandboxes: run everything in a container (or an OS sandbox) without network. This way, even an approved command can’t send your SSH keys to some random server.
- Scoped tools: instead of a generic
run_command, give it small tools likerun_testsorgit_diff. The model can’t ask for something that doesn’t exist.
The “YOLO mode” or --dangerously-skip-permissions flags just turn all of this off. It’s fine in a
throwaway container, but it’s a very bad idea on your laptop (ask me how I know).
Why two harnesses on the same model feel so different
If the loop is 30 lines, what are the other 100 000 lines of Claude Code doing? Basically, everything around the loop.
- The feedback loop: the model is only as good as what it sees after each action. One harness
sends the raw 400 lines of
npm testoutput. Another one only keeps the failing tests. Some run the type checker or a linter after every edit (Claude Code calls them hooks) and send the errors back as the next tool result. The model sees its mistake before you do. Same model, but it fixes the bug in 2 steps instead of 6. - The orchestrator: real harnesses have a tool like
AgentorTask. Inside, there is another loop, with a fresh conversation and a smaller prompt. The parent delegates, and only the child’s summary comes back as atool_result. - Everything else: the system prompt, the wording of each tool description, how errors are formatted, how a diff is displayed, when the conversation gets trimmed… Lots of small details. But together, they make a huge difference.
In a nutshell, if you change the harness but keep the model, it can feel like a different model. That’s also why the Model Context Protocol (MCP) exists: a standard way to plug external tools (your database, your issue tracker, your browser…) into any harness.
Long story short: Coding agent = harness + LLM
The harness is a while loop. The LLM decides when the loop stops, and the body is a switch with
a few tools. The model is the smart part. But what makes it useful is everything around it: the
tools, the feedback from your tests, and the permissions that stop it from doing something stupid.
I find it reassuring. There’s no magic in there, just a feedback loop. And now that I know what’s inside, I’m a lot less surprised by what my agent does (and doesn’t do).
Further reading
- How to Build an Agent - Thorsten Ball. The post that made it click for me
- Building effective agents - Anthropic
- ReAct: Synergizing Reasoning and Acting in Language Models - Yao et al., 2022. Where the loop comes from
About the author
Hey, I'm Maxence Poutord, a passionate software engineer. In my day-to-day job, I'm working as a senior front-end engineer at Orderfox. When I'm not working, you can find me travelling the world or cooking.
Follow me on Bluesky